Cellular Atlases: Who Reads the Language of Tissue Best express
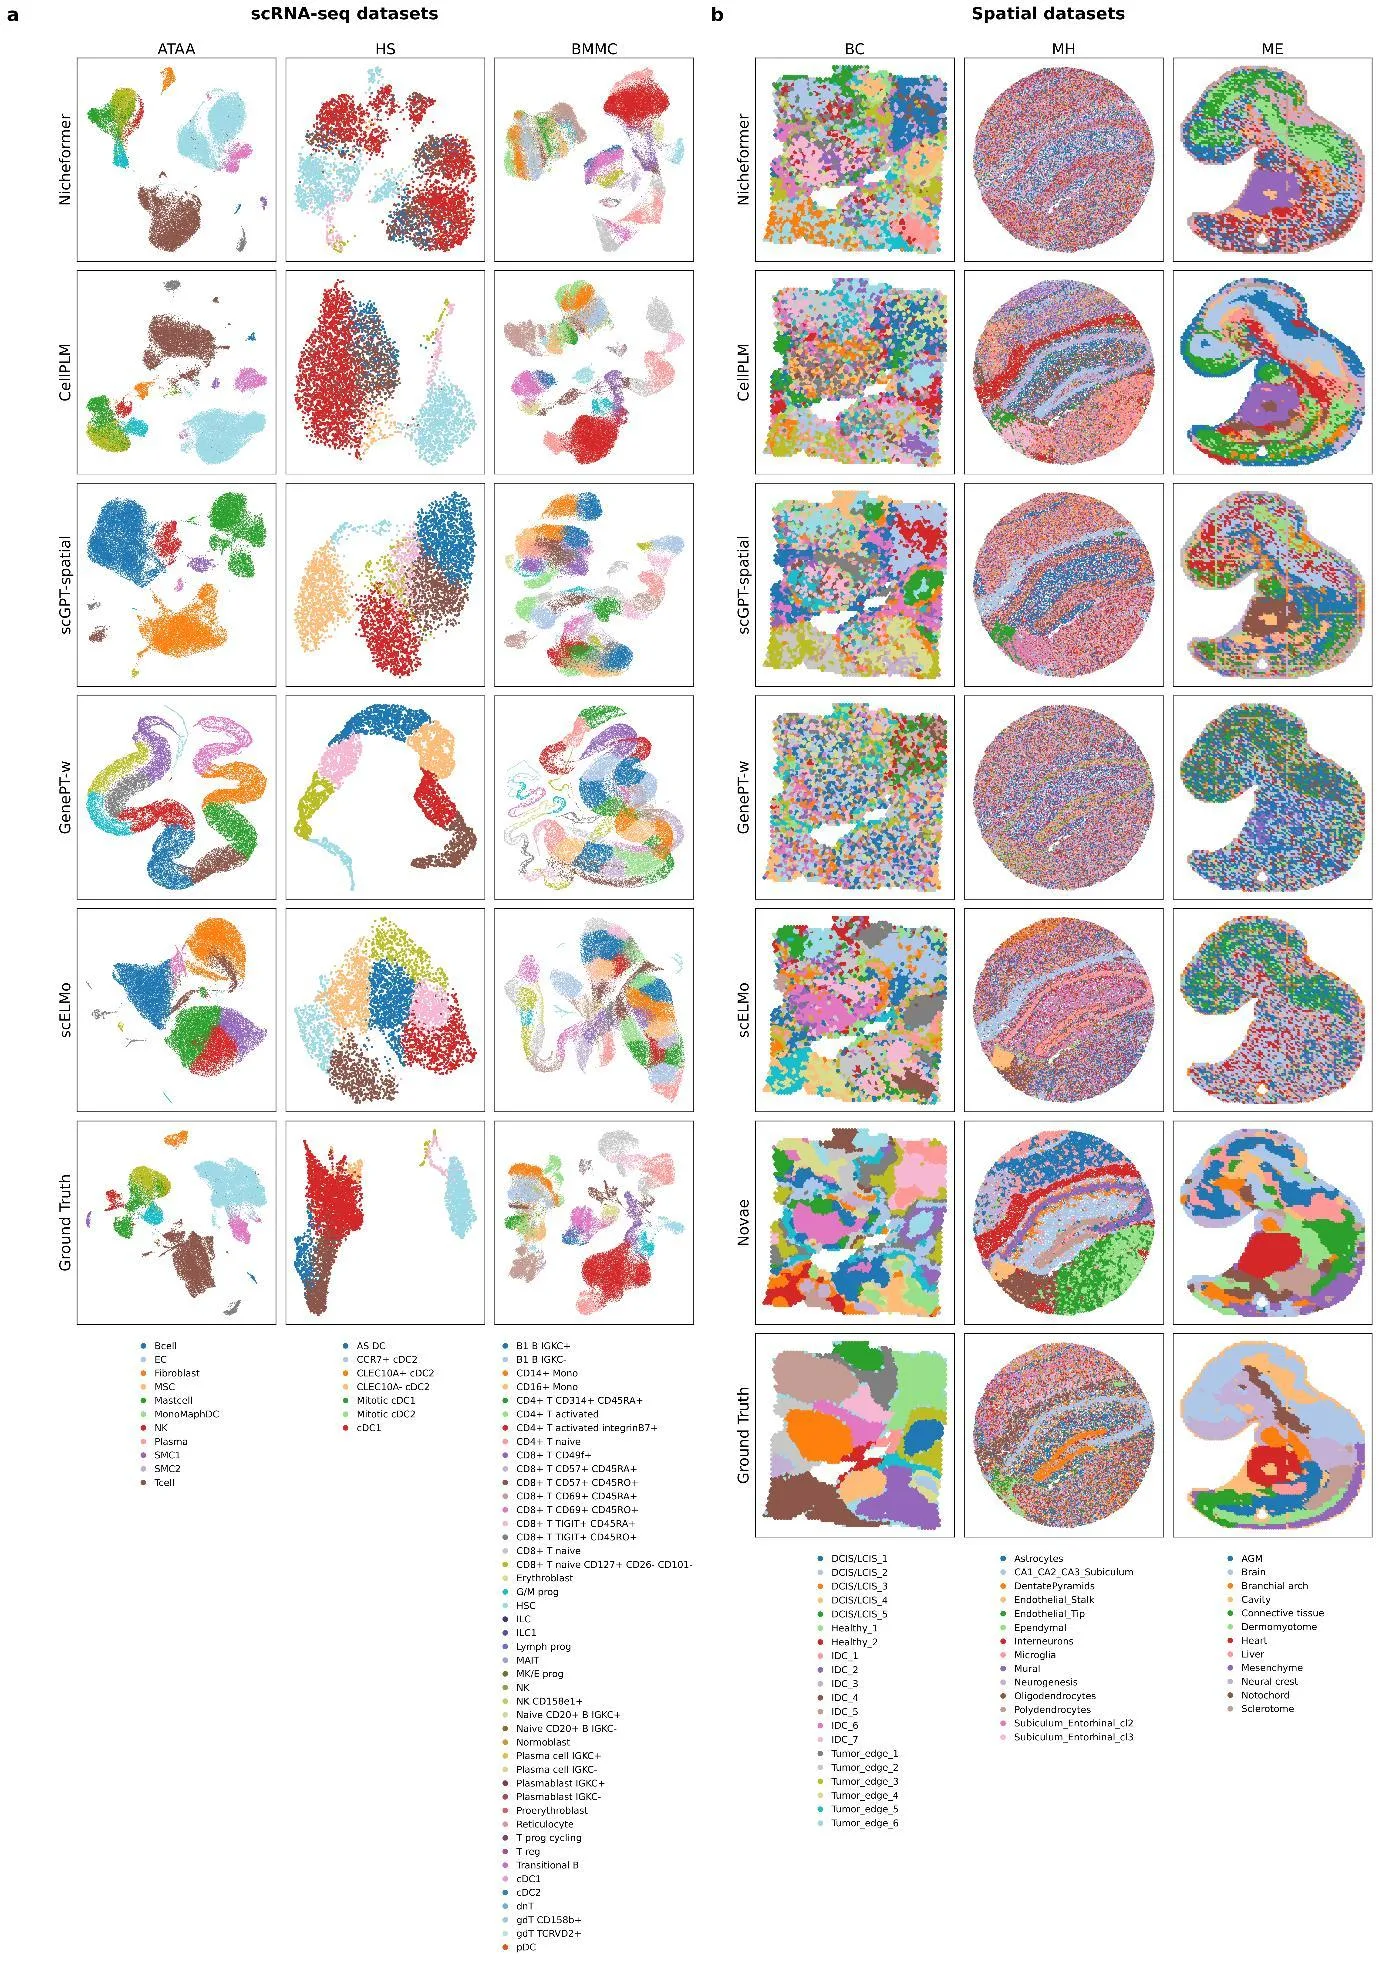
Biologists are increasingly trusting computers to read the "user manuals" of living cells. Six recent AI models (Nicheformer, CellPLM, scGPT-spatial, GenePT, scELMo, and Novae) are like six translators working from different dialects of the same cellular language. Each learned from its own corpus: some memorized sequences of active genes, others studied spatial maps of tissues, and still others started with plain human language.
The authors gave them a fair exam. The models were set the same tasks: cluster cells by type, find marker genes (molecular "passports" of cells), or predict how a cell will respond to a drug. The input data also varied — from simple lists of expressed genes to images showing the position of each cell within a tissue.
The results were sobering. Models trained on "flat" gene lists were best at determining cell types. Spatial models, which see the tissue map, more accurately preserved organ architecture. And language models, for which a gene is just a word in a sentence, unexpectedly did quite well at predicting drug effects. No model won in all categories, and the ranking shifted with the slightest nuances — the way data was preprocessed, the choice of metric, or even how genes were "chopped" into pieces for analysis.
This is not a race for an absolute champion. Rather, it's the emergence of a toolkit where each tool excels at its own job. The future belongs to models that can not only score points on tests but also explain to biologists why a cell took a particular developmental path.
Original abstract
as written by the authors arXiv:2607.17227
Single-cell and spatial foundation models promise transferable biological representations, yet their generality remains largely untested across modalities, biological domains and analytical tasks. We benchmarked six representative models, Nicheformer, CellPLM, scGPT-spatial, GenePT, scELMo and Novae, using a harmonised framework spanning scRNA-seq, spatial transcriptomics and Perturb-seq. We evaluated zero-shot and continually pretrained clustering, supervised annotation, marker-gene concordance and perturbation prediction. Model performance was strongly conditional: expression-trained cell-level transformers best resolved many cell-identity tasks, spatial and graph-aware models better preserved tissue architecture, and language-derived gene embeddings were competitive for selected perturbation-response metrics. No model dominated across tasks, and rankings shifted with modality, preprocessing, tokenisation, biological prior, domain shift and metric choice. This benchmark provides practical guidance for model selection and argues that future models should be judged by biological generalisation, interpretability and perturbation-grounded validity, not by scale or leaderboard performance alone.
Some models learned to understand genes simply by "reading" scientific papers. For them, a gene is like a word, and a cell is like a paragraph.