The standard error is a measure of how precisely you know an estimated quantity, such as the mean of a dataset. It is not the spread of the individual data points (that's the standard deviation), but rather the uncertainty in the estimate itself. If you repeatedly took new samples and computed the mean each time, the standard error tells you how much those means would vary. It is the standard deviation of the sampling distribution of the statistic.
History
The concept was formalized by British statistician Ronald Fisher in the 1920s, who introduced the term 'standard error' to distinguish it from the standard deviation of the data itself.
How it works
The standard error is calculated by taking the standard deviation of the data and dividing by the square root of the sample size (SE = σ/√N). This formula arises because averaging many independent measurements reduces the random noise. The more data you have, the narrower the distribution of possible means becomes, so the standard error shrinks. It is the key number for constructing confidence intervals and performing hypothesis tests.
In practice
It is used in every scientific field that reports averages — from clinical trials (the error bars on drug efficacy) to economics (the uncertainty in unemployment rate estimates).
Fun fact
The standard error of the mean is always smaller than the standard deviation of the data, which is why averaging is such a powerful tool for reducing noise.
The orchestra plays without a conductor. Each instrument follows its own schedule: the violin on Monday, the flute on Wednesday, the timpani on Saturday. Astronomers hear not music but isolated notes scattered across the calendar. A telescope sees a star only when it is above the horizon and when the schedule has allotted time for it.
In the 1980s, the DARPA speech recognition challenge settled the debate between statistical methods and hand-written rules, setting a common standard for the entire field.
In winter, one part of town gets three times as much snow as the neighborhood next door. One year is a scorcher, the next is a cold snap. That's the whims of weather. But over decades, a different, slow shift emerges: winters, on average, get milder. Telling the two apart is the central challenge for climate scientists.
As you slowly turn the tuning knob of an old radio, the sound doesn't fade in gradually from the static: it bursts forth in a sudden jump, the moment the antenna hits resonance with the wave. Genes in a living cell behave much the same way.
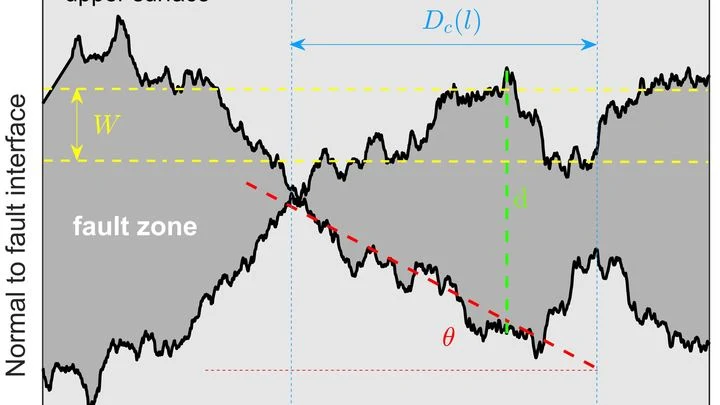
Two pieces of sandpaper are pressed tightly together. As you start to slide them, they first catch on the rough spots, then suddenly slip. A fault in the Earth behaves much the same way during an earthquake. But there's a crucial detail: how far do you need to push the edges before the grip gives way? This distance is called the critical slip distance.
A stable system behaves like a ball in a bowl: give it a push, and it rolls back to the bottom. The spread of possible trajectories, uncertainty, shrinks over time. But the speed depends on the slope of the bowl's walls. In complex systems, this 'bowl' has sections of varying steepness.
When you're planning a renovation, you don't buy paint by eye: you measure the wall area. In science, deciding how many samples to collect is a similar guess, but the stakes are higher. Skimp on samples, and your study becomes a lottery: you might miss a real effect, or you might mistake noise for a discovery. Overshoot, and you're wasting tubes, months, and, in animal experiments, lives.
A stone falls into a pond, and the ripples on the water tell for a long time where it sank. With a black hole, it would seem, things are different: everything that crosses the horizon (the boundary from beneath which not even light can escape) vanishes without a trace.
In an orchestra where every musician plays the same note, the sound merges into a powerful unison. This is how a Bose–Einstein condensate is born: many boson particles at extremely low temperatures behave as a single entity.
Eyes follow a dot that smoothly traces a complex curve on the screen. For most people, the gaze stays close to it, but for some, it seems to slip or lag behind. Previously, such peculiarities drowned in average numbers: if you add everyone up and divide, the difference almost disappears.
Instead of looking at averages, the scientists decided to examine each person individually.
For a long time, the Universe was seen as a strict baker: it was thought that in every corner, stars were mixed from the same recipe — for each giant star, there were roughly the same number of dwarfs, no matter where they were born.
Water swirling into a vortex eventually stops being smooth: foam and spray appear. Mathematicians describe such flows with equations, but there's a puzzle — sometimes the solution 'explodes,' becoming infinite, and no one knows why. Stochastic modeling doesn't help here; we need a precise tool.
A neutron star is a sphere the size of a city, but it weighs as much as one and a half Suns. Inside such a sphere, matter is so compressed that a teaspoon of it would weigh billions of tons. But physicists don't fully know what this matter is made of.
Imagine an interpreter who gets distracted by every rustle in the hall. The more rustles, the more errors in the translation, even though the meaning of the speech hasn't changed. The same happens with data: if measurements are unevenly spaced, standard analytical tools start "hearing" changes that never occurred in the underlying process.